Vienna, Austria
Head of Enterprise, everii Group.
Twenty years in one codebase.
I've spent the last two decades building TEAMBOX, the ERP platform for service providers that's become the PSA market leader in DACH — starting as one of its earliest developers, now running enterprise-level client and product work, CI/CD, and the team behind it. My current focus is agentic engineering: building AI-driven development workflows into a live, twenty-year-old codebase without breaking it.
20+ years, one productPHP & DevOps300+ enterprise clientsAgentic engineering focus
Work Highlights · September 24 – October 8, 2026
The latest work
Updated monthly, straight from the actual work — not a highlight reel.
Featured build
AI agents sign in over OAuth instead of a pasted API token
Connecting an AI agent to our MCP server used to mean a personal API token, a Node.js bridge and a hand-edited config file. Teams without a developer could not finish that, and the token opened the whole API, not just the agent tools.
- Standard OAuth, built in six stacked steps. Discovery metadata, self-registration for agent apps, a consent screen, 15-minute access tokens and rotating refresh tokens. A reused refresh token ends the whole connection.
- Agent tokens work only on the agent endpoint. The token names its audience, and every other entry point rejects it. A new endpoint that forgets the check fails closed.
- Tools follow the customer's modules. Each tool declares the module, permission and settings it needs. A switched-off tool answers exactly like one that does not exist. One summary tool loaded up to 10,000 rows into PHP to add them up; it is now one SQL query.
Users see and revoke connected agents in their settings. The OAuth steps and 13 new tools (30 in all) now land as one change, in final review and QA on staging.
Read the full writeup →Featured build
An audit of the API's permission checks, one failing test per gap
An inventory of the API's endpoints looked at every operation the interface uses, not just the ones that looked risky. Every permission gap it found was first proved with a failing test, then fixed.
- Inventory first. Each operation is listed with who may call it and what it reads or writes, so the audit covers everything instead of a sample.
- A failing test before every fix. Each gap became a test that fails on the old code and passes on the new. Review found more cases of the same kind, and they went through the same loop.
- Writes only what they exist for. Where an operation saved more than it needed to, it now writes only its own field.
The permission tests run to about 700 lines, and every test seeds its own data, so none of these gaps can quietly come back.
Keeping secrets out of logs and AI chat transcripts
A review of what reaches central logging, and what reaches AI chat transcripts, found places where credentials could end up. The logger now masks credentials in messages and exceptions before writing them. The repository's AI agent commands for releases, KPIs and reviews no longer ask anyone to paste a token into the chat: they read secrets from files created outside the agent, refuse files other users can read, and never print the value.
Agentic Strategies
How I actually build and work with AI agents
Long-form writeups on the methodology — scoping, review discipline, verification, documentation architecture — for anyone doing this kind of work themselves, not just a list of what got built.
Agentic Strategies
Writing for the Reader: What Changed When Agents Started Writing My Tickets
Nothing the agents wrote was wrong. It was just too long to read. A shape and a limit for each kind of text, the one habit behind most of the length, and why the fix for long titles was not in the title.
Read the full writeup →Agentic Strategies
Definition of Done: Why a Checklist Decides When AI-Assisted Work Is Finished
An agent reports success the moment it stops working — that isn't the same claim as finished. A fixed set of gates instead of the agent's own judgment, the operating model behind it, and the codebase habits that make agent work easier or harder.
Read the full writeup →Agentic Strategies
Context, Decisions, and Guardrails: Why Agents (and New Hires) Shouldn't Re-Derive Your Codebase From Scratch
Every fresh AI agent session on a legacy codebase faces the same choice: re-analyze everything from the code alone, or read what's already been decided. One canonical guide, read consistently by three different AI tools, and a strict split between what's being asked for, what's been decided and why, and how a specific piece of work is scoped.
Read the full writeup →Agentic Strategies
Instructions, Style, and Memory: How I Keep Several AI-Assisted Projects Consistent
Running several AI-assisted projects at once creates a specific failure mode: each one drifts its own way, and every session re-explains context the last one already worked out. Persistent per-project instructions, one shared style guide, and a memory system that carries lessons across sessions — the scaffolding that stops it.
Read the full writeup →Personal AI Research · Proof of Concept, July – October 2026
Outside TEAMBOX: independent AI research builds
A way to stress-test what Gemini can actually do on real, messy problems instead of toy demos — built independently of TEAMBOX, in Google AI Studio. Keeping both of these consistent with each other, and with the rest of this site, runs on the practice covered in Agentic Strategies →.
Personal AI Research
OSINT Real-Time Tracker — multilingual conflict monitoring, built solo with Gemini
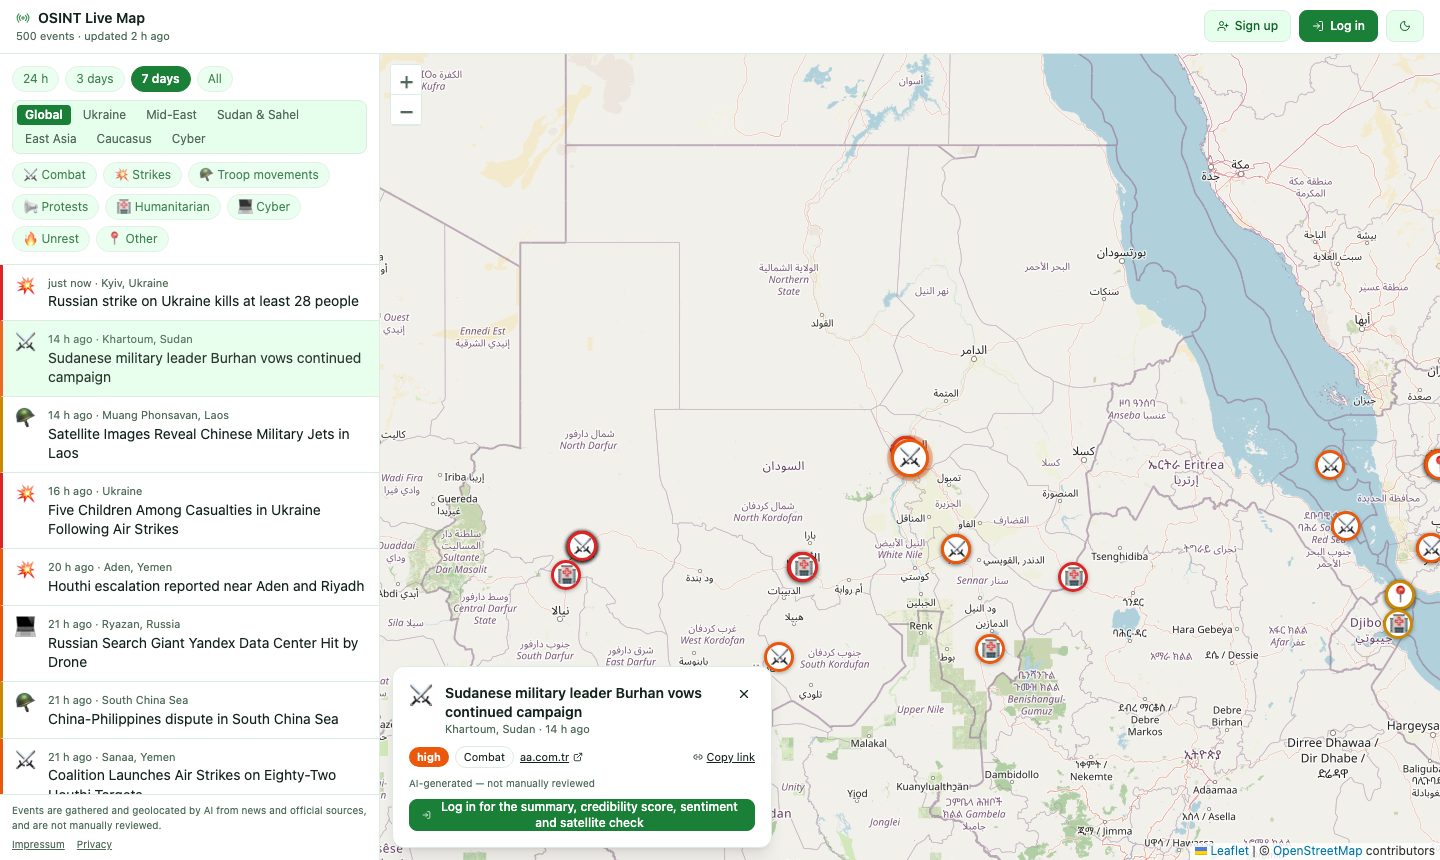
A maps-based dashboard that monitors global conflict events close to real time. It takes open-source reports — social posts, wire dispatches, radio transcripts — in whatever language they were written, and turns them into structured, geolocated, credibility-scored events a researcher can actually use.
- Multilingual intake, no separate translation step. Signed-in users paste raw source text in Ukrainian, Arabic, French, Hebrew, or English and Gemini handles extraction directly — entities, location, and language nuance in one pass, not a translate-then-analyze pipeline.
- NLP-based geolocation. Gemini resolves place names and context clues into exact coordinates, with the reasoning behind each resolution shown, not just a pin dropped on a map.
- Sentiment and tension scoring beyond positive/negative. Each report gets a sentiment score, a 1–10 tension score, a dominant emotion, and a read on native-language slang and nuance that keyword-based tools miss entirely.
- A transparent, five-parameter credibility grade. Every event is scored 0–100 across source reputation, cross-referencing, evidence level, contextual plausibility, and freshness — with the reasoning shown, not a black-box trust score.
- An autonomous harvester, not just a manual tool. An external scheduler runs the same search-grounded pipeline every three hours, unattended. An event is kept only if its source is a real article from GDELT or ReliefWeb, or one of Google's own search citations, stored as the publisher's address. Every harvest and its audit trail are saved to Firestore.
- A public live map, with the analysis behind a login. Anyone can browse recent events by time, region and category. The summary, credibility score, sentiment and satellite check are for registered users.
This is a personal research prototype, not a production intelligence product. When the model is unavailable, the app shows the data it already has and invents nothing. Built end-to-end (React, Express, Gemini API, Firestore), deployed to Cloud Run, with a monthly spending cap on every model call.
View live app → Read the full writeup →Personal AI Research
Crimes of the 1% — a structured, sourced database of financial crime and litigation among the ultra-wealthy
A database that catalogs corporate and executive-level financial crime — fraud, market manipulation, tax evasion, state capture — against the actual enforcement outcome on record: criminal conviction, settlement, deferred prosecution, or litigation still in progress. Built the same way as the OSINT tracker: solo, in Google AI Studio, testing whether an LLM can hold a large, sourced, structured dataset together instead of just summarizing text.
- Sourced by design, not by afterthought. Every case record carries one or more citations classified by document type — DOJ filing, SEC order, court judgment, EPA record, ICIJ archive — instead of a single unlabeled link.
- Beyond a dollar figure. Each entry converts a financial penalty into a systemic-impact score and the years a worker on an illustrative $10,000 a year would need to earn it. A companion inequality dashboard turns the dataset into charts by sector and crime type, plus a deep-time view of how far back in Earth's history that worker would have had to start.
- Two Gemini-powered lenses on the same data. An AI Fact-Finder modal answers ad-hoc questions against the dataset, and an AI Patterns modal surfaces cross-case trends — which sectors recur, which enforcement types are most common — the same "structured reasoning over messy real data" test as the OSINT build.
- A submission path, not a closed dataset. A case-submission form lets anyone add a new entry directly — published immediately with an "AI-generated, unreviewed" disclosure badge, so the dataset isn't limited to whatever I find on my own research pass.
- Amounts and sources that hold up. An AI-found case shows a penalty only when its source states one, and its source must name the company or person. A source that has gone dead says so instead of linking nowhere.
Early-stage research build — React, TypeScript and Firebase/Firestore, seeded with an initial dataset rather than a continuously fact-checked ledger. Treat individual case entries as a starting point for your own verification, not a settled record.
View live app → Read the full writeup →Side Projects · September 2026
Outside TEAMBOX, outside research: things built for fun
Not every personal build is a research prototype. Some are just for the enjoyment of building something that works and is fun to use.
Side Project
Wirefront — a browser vector-tank shooter with live co-op, built together with Claude
A homage to 1980s vector-scope arcade combat games. Drive and fire across a wireframe battlefield against wave-based enemy tanks — the cannon points wherever the hull points, so aiming is driving. No installs, runs straight in the browser, keyboard or touch controls.
- Real hidden-line removal, not a wireframe shader. Three.js
EdgesGeometryplus a void-colored occlusion fill, so solid faces hide whatever sits behind them — the look of a 1980s vector cabinet, done with today's rendering. - Every sound synthesized, no audio files. Engine hum, cannon fire, and explosions generated live with the WebAudio API.
- A shared, append-only leaderboard. Firestore security rules validate the document shape on write and block updates or deletes outright, so a score can be added but never altered.
- Live co-op presence. Firebase Realtime Database puts everyone with the page open into one shared global room as a real ally tank, with join/leave comms and client-side collision between allies.
The single-player game and the co-op presence layer above are both live. A fully shared world — where every player fights the same enemies on the same wave — is the next phase, not yet built.
Play → View on GitHub →Side Project
Ripple Type — a WebGL text effect built after staring at a TV title card for thirty seconds
Type any word and it ripples outward in ink and dust — a homage to the title-card treatment in Pluribus, rebuilt from scratch by looking at the effect and asking how it would actually work, not from any production asset.
- The hatching is real displacement, not a filter. A hand-written GLSL fragment shader samples a procedural line pattern at a per-pixel radially-displaced UV, so the lines genuinely bend where the wave passes through.
- The background rings aren't drawn — they're the wave. A hashed per-cell dot field renders at a density driven by the same scalar ripple value used for the text displacement, so the concentric rings and the letter distortion come from one shared field.
- Two ripple layers, not one. A constant low-amplitude ambient wave keeps the text alive at rest; click anywhere to layer a stronger, decaying ripple on top.